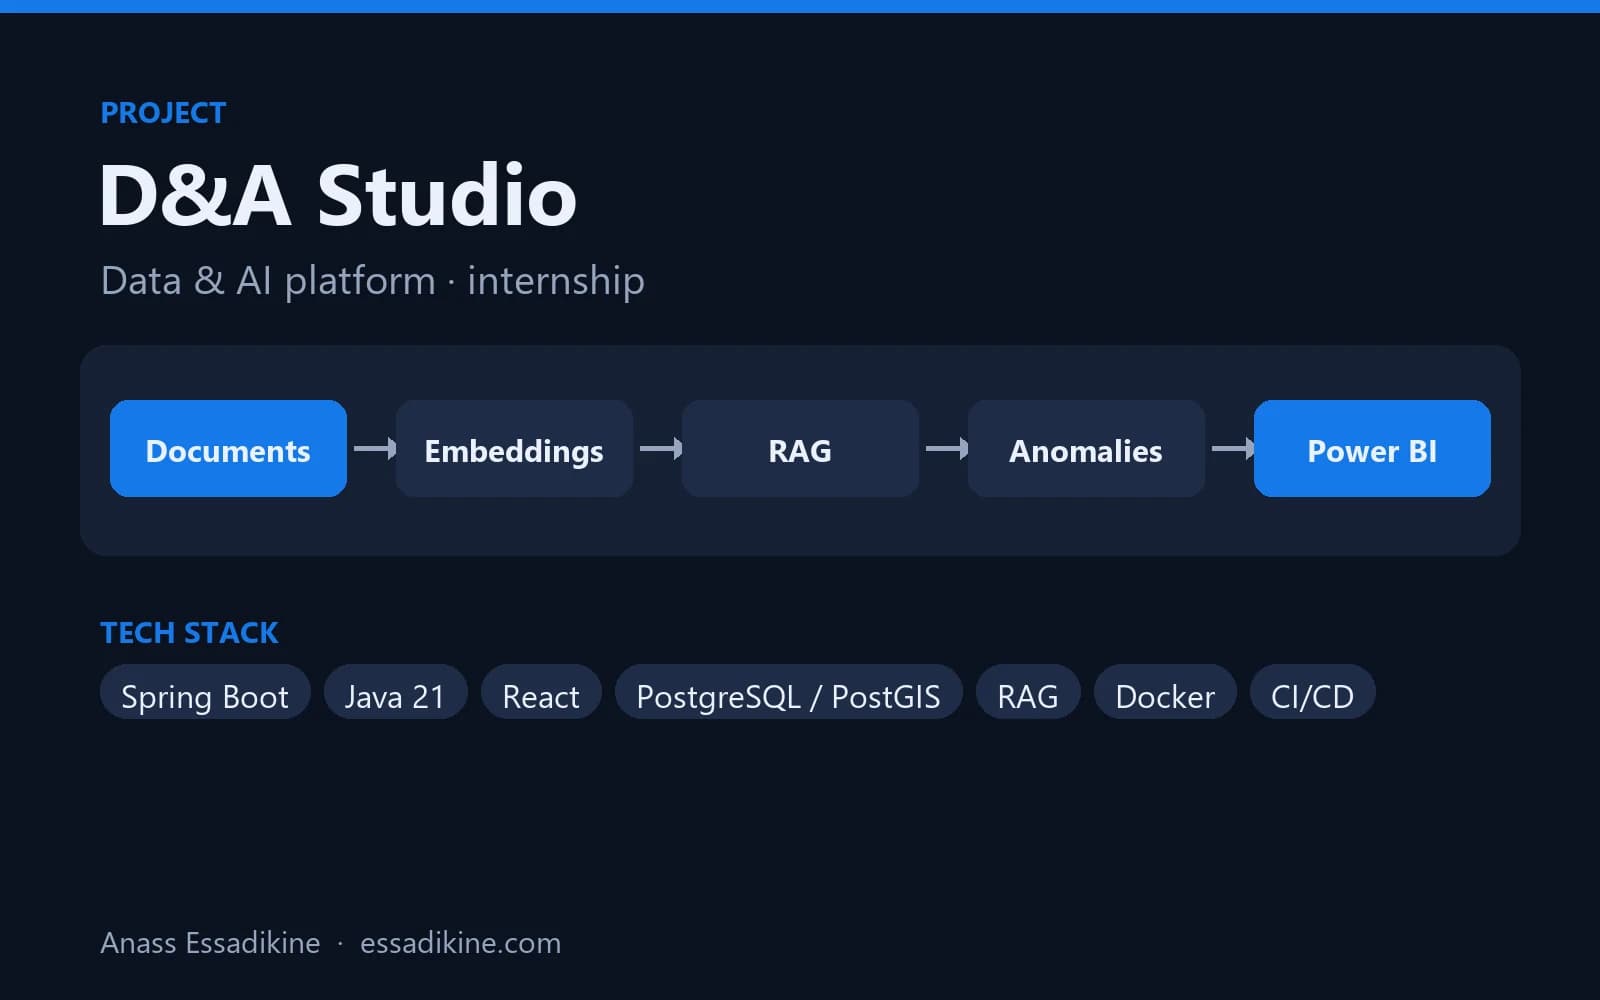
 AI & AutomationInternship · 2026
D&A Studio — Data & AI Platform (PaaS)
A platform that brings geospatial tracking data, an AI assistant on company documents, anomaly detection and BI dashboards into one place.
Spring BootJava 21ReactPostgreSQL+8
ETL/ELT pipelines, data warehouses and data-quality checks in Python and SQL, so your reports always run on clean, up-to-date data.
In short
I design and build data pipelines that collect data from your files, APIs and databases, clean and model it, and load it into a warehouse ready for reporting. Pipelines are written in Python and SQL, scheduled, monitored, and include data-quality checks so problems are caught before they reach your dashboards.
1. Audit
Sources, volumes, refresh needs and current issues.
2. Design
Target model, pipeline steps and checks.
3. Build
Python/SQL pipelines, tests and scheduling.
4. Run
Monitoring, alerts and handover.
From 2,500 MAD for a first automated pipeline
AI & AutomationInternship · 2026A platform that brings geospatial tracking data, an AI assistant on company documents, anomaly detection and BI dashboards into one place.
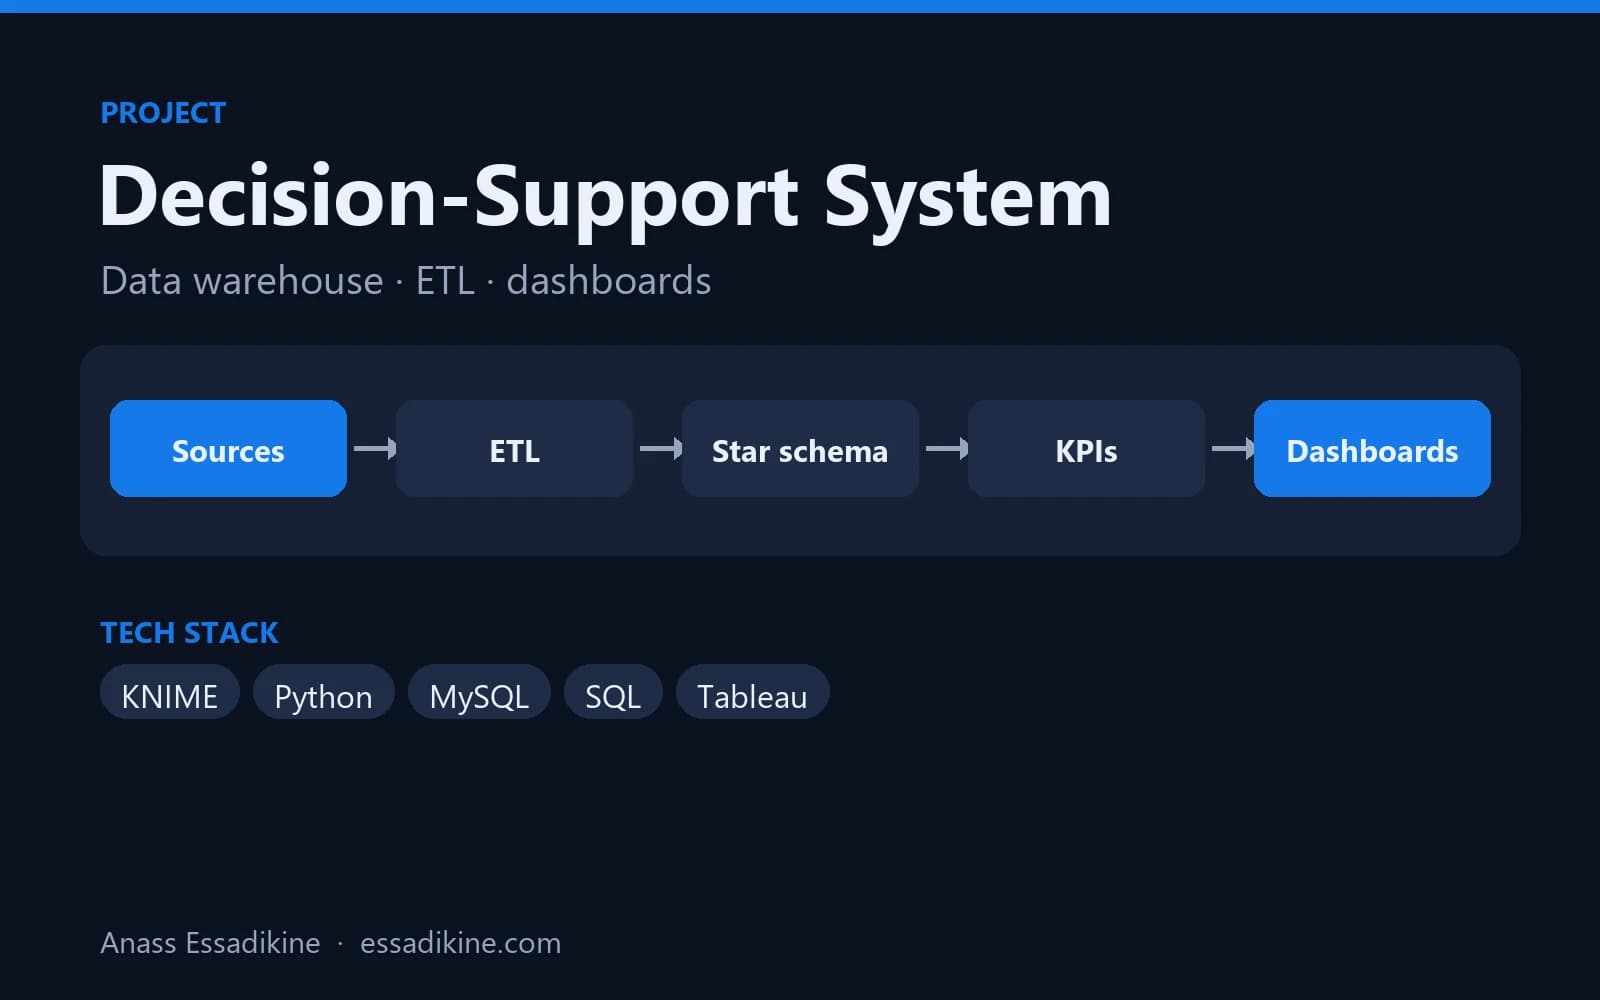 Data Analytics & BIAcademic project · 2025
A star-schema data warehouse fed by ETL flows, with analytics dashboards for decision-makers.
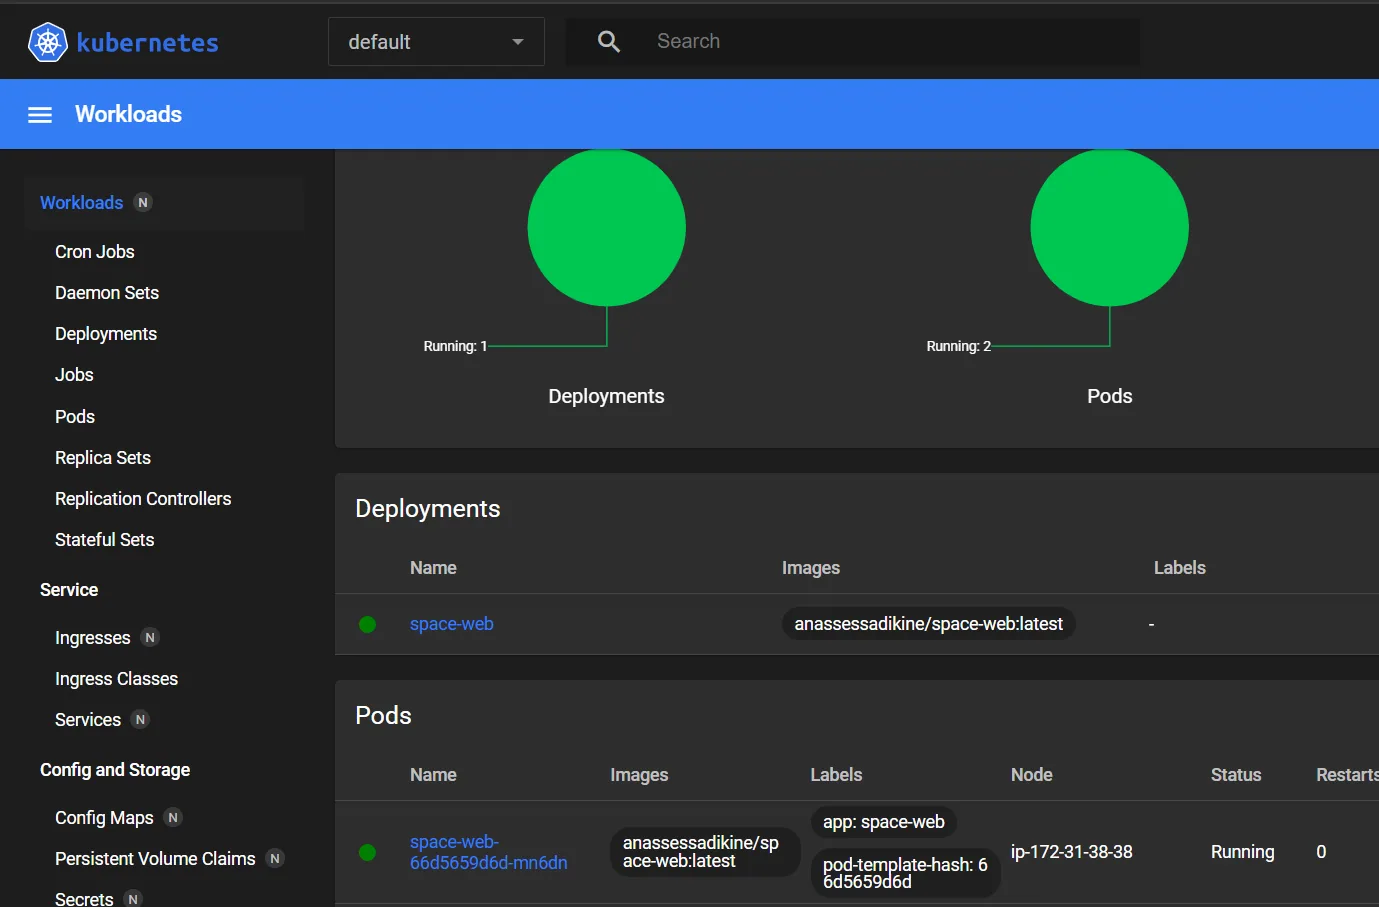 Cloud & DevOpsAcademic project · 2024
An end-to-end pipeline that builds, containerises and deploys a React app to Kubernetes on AWS on every push.
 Business Intelligence
Most slow or wrong Power BI reports have a modelling problem, not a visual problem. Here is how I go from raw exports to a clean star schema and trustworthy KPIs.
Read article Data Engineering
Wrong numbers in a dashboard destroy trust faster than slow reports. Here is the layered approach I use: rules first, statistics second, machine learning only when needed.
Read articleMainly Python (pandas, PySpark when volumes require it), SQL, Airflow or simple schedulers, and PostgreSQL, MySQL or SQL Server as warehouse. I pick the lightest stack that fits your volumes.
Whether you need a full-stack web app, a data dashboard, or a cloud-native deployment — I'd love to hear about it.